RAG, Fine-Tuning, or Off-the-Shelf: How to Add AI to Your Product Without Regret
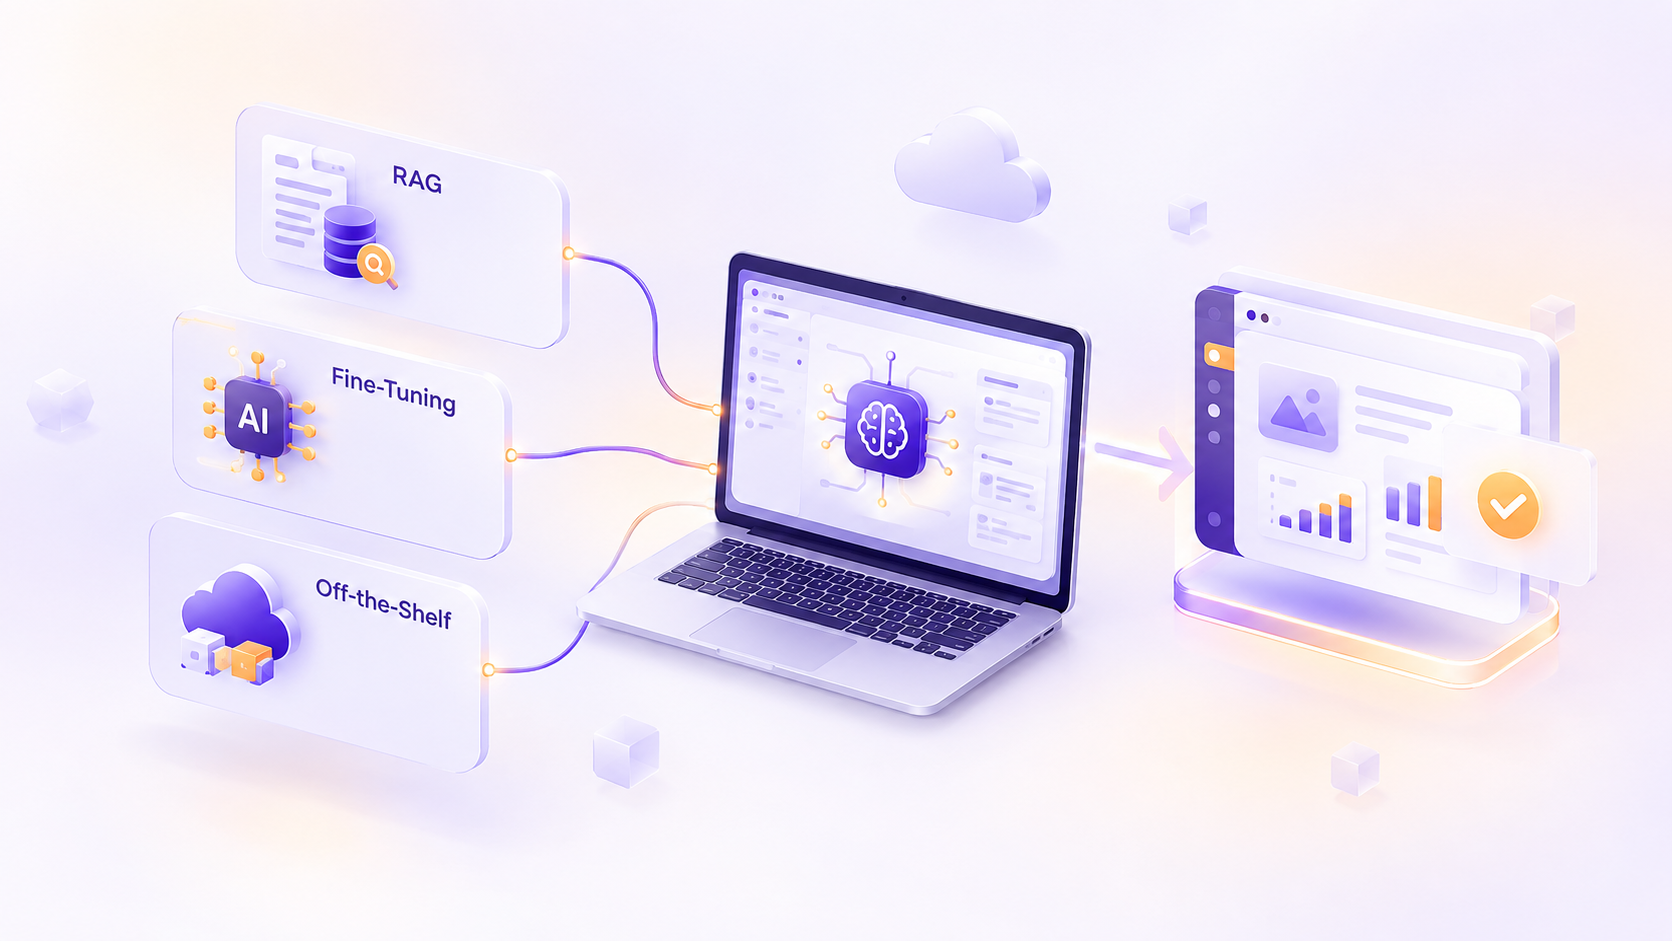
Most teams don't regret adding AI to their product. They regret how they added it.
Picture a team that spends three months fine-tuning a model on old support tickets. The launch goes fine until a customer asks about the refund policy that changed last week. The model confidently recites the old one, because nothing in its training knew any better. Now picture a second team that builds a full retrieval pipeline with a vector database, only to discover that a well-written prompt would have solved the problem in an afternoon.
Both teams made reasonable decisions with the information they had. Both ended up doing rework they could have avoided.
This guide is here to save you from that. We'll walk through the three main ways to bring a language model into your product (off-the-shelf, RAG, and fine-tuning), explain what each one is actually good at, and give you a simple way to decide which one to start with.
The short answer
If you only have a minute, here's the whole framework:
- Start with an off-the-shelf model and a strong prompt. It's the fastest way to learn what your users need, and it often goes further than people expect.
- Add RAG when the model lacks knowledge. That means private, fresh, or very large bodies of information it was never trained on.
- Fine-tune when the model has the knowledge but not the behavior. Think consistent tone, strict formats, or cheaper and faster responses at high volume.
- Combine them later, not first. Many mature products use two or all three, but they got there step by step.
The rest of this post explains why, so you can defend the decision to your team and your budget holder.
The three options in plain English
Before comparing them, it helps to have a clear picture of each one. A useful analogy is hiring a smart contractor.
Off-the-shelf: the smart contractor
With an off-the-shelf approach, you call a hosted, pre-trained model through an API and shape its behavior with instructions. You write a system prompt, add a few examples, ask for structured output, and connect it to tools like your search or your database. The model itself doesn't change.
It's like hiring a very capable contractor who's smart and fast but knows nothing about your business. You can brief them well, but that's all they have to go on.
RAG: the contractor with a binder
RAG stands for retrieval-augmented generation. Before the model answers a question, your system searches your own content (help articles, product data, contracts, internal docs) and hands the most relevant pieces to the model along with the question.
It's the same contractor, now with a binder of your company's documents open on the desk. They aren't smarter, but they can look things up. That's why RAG is often described as an open-book exam.
Fine-tuning: the contractor you trained
Fine-tuning means taking a model and training it further on your own examples, so a pattern becomes part of how it behaves. You might show it a few hundred examples of ideal replies in your brand voice or thousands of correctly labeled support tickets.
This is the contractor you trained on your way of working until it became second nature. They don't need reminding how you like reports formatted. But teaching takes time, and if your processes change, you have to retrain.
The one question that decides most of it
When teams get stuck choosing, one question usually clears things up: is the problem about knowledge or about behavior?
Knowledge problems sound like this:
- "It doesn't know our pricing, policies, or product catalog".
- "It can't answer questions about documents we wrote last month".
- "It makes things up when asked about our internal processes".
These point toward RAG, because the fix is giving the model access to the right information at the right moment.
Behavior problems sound like this:
- "The answers are correct, but the tone is off-brand".
- "It keeps breaking the JSON format our app depends on".
- "It labels the same type of request differently every time".
These point toward better prompting first, then fine-tuning if prompting can't close the gap.
Neither sounds like "It's pretty good already". In that case, ship it. You can always improve it once real users show you where it falls short.
This one distinction prevents the most common expensive mistake, which is trying to fix a knowledge gap with fine-tuning.
How the three options compare
| Off-the-shelf | RAG | Fine-tuning | |
| Best for | Getting started, general tasks, prototypes | Answers grounded in your own, changing content | Consistent style, format, and specialized behavior |
| Time for the first version | Hours to days | Days to weeks | Weeks, plus time to prepare data |
| Upfront effort | Low | Medium | High |
| Handles changing information | Only if you pass it in each time | Yes, update the content, and you're done. | Poorly, changes usually need retraining. |
| Ongoing maintenance | Prompt tweaks | Content pipeline and search quality | Data upkeep and retraining |
| Biggest risk | Generic or inconsistent answers | Poor retrieval leading to wrong answers | Training on weak data, or teaching facts that are stale |
Treat the table as a directional guide. Actual effort depends on your data, your team, and the provider you use.
Why off-the-shelf should be your default starting point
It's tempting to skip straight to the more sophisticated options. Resist that for three reasons.
You learn faster. A working prototype in front of real users teaches you more in a week than a month of planning. You find out which questions people actually ask, where the model struggles, and whether the feature matters at all.
Modern models go a long way. With clear instructions, a few good examples, structured outputs, and tool calling, an off-the-shelf model can handle a surprising range of product features, from summarization to classification to drafting to extraction.
You need a baseline anyway. To know whether RAG or fine-tuning is helping, you need to measure what the plain model does first. Otherwise you're guessing.
You've probably outgrown the simple approach when:
- Quality has plateaued no matter how much you refine the prompt.
- Your prompt has grown so long that it's slow, expensive, or hard to maintain.
- The model needs information it simply doesn't have.
- Output is inconsistent in ways that break your product.
- Costs or response times become a problem at your volume.
Notice that each of those is a specific, observable problem. That's the standard to hold yourself to before adding complexity.
When RAG is the right call
RAG shines when your product needs to answer from information that is private, recent, or too large to paste into every request.
Good fits include:
- A support assistant that answers from your help center and policy documents
- An internal search tool that lets employees ask questions across company docs
- Product Q&A grounded in a catalog or specification database
- Any feature where users need to see where an answer came from
RAG has real advantages. You can update your content without touching the model. You can show citations, which builds trust. You can also control who sees what, since retrieval can respect user permissions. And when something goes wrong, it's easier to audit, because you can inspect exactly which documents were retrieved.
The catch: most RAG failures are search failures.
The model can only work with what retrieval hands it. If the search step returns the wrong passages, the answer will be wrong, and it will sound confident anyway. The usual culprits are
- Poor chunking. Documents split in awkward places lose the context that makes them useful.
- Stale or duplicated content. If your knowledge base contradicts itself, so will your assistant.
- Weak retrieval. Pure semantic search can miss exact terms like product codes or names, which is why many teams combine it with keyword search.
- Too much or too little context. Stuffing in ten documents can be as harmful as providing none.
One more thing worth saying: if your content is small and stable enough to fit comfortably in the model's context window, you might not need retrieval at all. Sometimes the simplest version is just including the material in the prompt.
When fine-tuning earns its place
Fine-tuning is powerful, but it's a specialist tool. It works best when you want to change how a model responds, not what it knows.
Good fits include:
- Consistent voice. A brand tone that prompting alone can't hold steady across thousands of responses.
- Strict formats. Outputs that must follow a precise structure every time.
- High-volume classification or extraction. Tasks with clear right answers and plenty of labeled examples.
- Efficiency at scale. Training a smaller, faster model to match the behavior of a larger one on a narrow task, which can cut cost and latency.
Before you commit, be honest about what it requires:
- Good training data. Fine-tuning amplifies whatever you feed it, including your mistakes. A smaller set of carefully reviewed examples usually beats a large, messy one.
- A way to measure success. Without a test set, you can't tell whether the tuned model is actually better.
- A plan for maintenance. When your requirements change or the base model is replaced, you may need to retrain.
Also keep in mind that fine-tuning options, pricing, and supported models vary by provider and change often, so check the current details before you plan around them.
The mistake to avoid
Don't fine-tune to teach the model facts. Facts change, and a fine-tuned model won't reliably recall them anyway. Put facts in a retrieval system where you can update them, and use fine-tuning for behavior.
Combining approaches without overbuilding
These options aren't rivals. Plenty of strong products use more than one.
A customer support assistant is a good example. RAG supplies accurate, current answers from your policy documents. A fine-tuned smaller model handles tone and response structure so replies feel consistent and cost less to run. An off-the-shelf model with a well-designed prompt handles everything in between.
The lesson is about order, though. Get the simple version working, find out what's actually broken, and add one layer at a time. Every new component is something your team has to monitor, debug, and pay for.
Six regrets to avoid
Here are the patterns that most often lead to rework.
- Fine-tuning to fix a knowledge gap. Covered above, and worth repeating because it's so common.
- Building RAG before defining "good". Without example questions and expected answers, you can't tell whether your retrieval is improving.
- Skipping evaluation. If you can't measure quality, every change is a gamble. Even a modest set of real, representative examples gives you something to test against.
- Ignoring data privacy and permissions. Know what data leaves your systems, what your provider retains, and make sure retrieval only surfaces content a given user is allowed to see.
- Locking yourself to one model or vendor. Models improve fast. Keep your prompts, evaluation set, and integration layer organized so you can swap components without starting over.
- Building for the demo instead of the job. A flashy prototype that doesn't fit into your users' workflow won't get used, no matter how clever the architecture.
A practical path from idea to launch
If you want a sequence to follow, this one works for most teams:
- Define the job. Write down what the feature should do and how you'll know it's working. Be specific: "reduce time spent answering repeat questions" beats "add AI".
- Collect real examples. Gather a set of realistic inputs along with what a good output looks like. Fifty well-chosen examples is a solid start.
- Build the baseline. Use an off-the-shelf model with a clear prompt and see how it scores.
- Diagnose the failures. Sort the misses into two piles: things the model didn't know, and things it knew but handled badly.
- Fix the biggest pile first. Knowledge gaps call for RAG. Behavior gaps call for prompt refinement, then fine-tuning if needed.
- Test again, then release. Compare against your baseline, launch to a small group, and watch real usage.
- Keep monitoring. Track quality, cost, and user feedback, and revisit your approach as your product and the models evolve.
Don't overlook security and data handling
Adding AI to a product means new data flows, and they deserve attention early rather than after launch.
- Review what information is sent to your model provider and how it's stored or used.
- Remove or mask sensitive personal data wherever you can.
- Apply access controls inside your retrieval layer so users can't pull up documents they shouldn't see.
- Be aware that retrieved content can contain instructions written by someone else, which is a known attack pattern called prompt injection. Treat retrieved text as untrusted input.
- Log enough to investigate problems without collecting more personal data than you need.
A quick decision checklist
Use these questions as a final gut check:
- Have I built and measured a simple off-the-shelf baseline? If not, start there.
- Is the model missing information about my business, my customers, or recent events? Consider RAG.
- Does the model know enough but respond in the wrong style, format, or consistency? Try better prompting, then fine-tuning.
- Do I have enough high-quality examples to train on, and a way to test the result? If not, hold off on fine-tuning.
- Am I adding complexity to solve a problem I can name and measure? If not, pause.
The bottom line
Adding AI to your product doesn't require picking a side in the RAG versus fine-tuning debate. It requires understanding your problem well enough to reach for the right tool, at the right time, in the right order.
Start simple. Measure honestly. Add knowledge with retrieval and behavior with fine-tuning, and only when you can point to the specific gap each one fills. Do that, and you'll spend your budget on improvements your users notice instead of rework your team dreads.
If you're planning an AI feature and want a second set of eyes on the approach, the team at Raydiant Webs is happy to talk it through.
Frequently asked questions
Related Blog
AI Automation for Small Business: 12 Processes Worth Automating First
The highest-ROI processes to automate first are the ones that are repetitive, high-volume, and rule-based enough that a human doing them mostly follows a…
How Much Does AI Development Cost in 2026? Real Project Ranges
AI development in 2026 costs anywhere from roughly $10,000 for a focused pilot to $500,000 or more for an enterprise-grade platform, and almost none…
0 Comments
Please log in to post a comment